Why AI Metrics Often Mislead Organizations
20 August 2026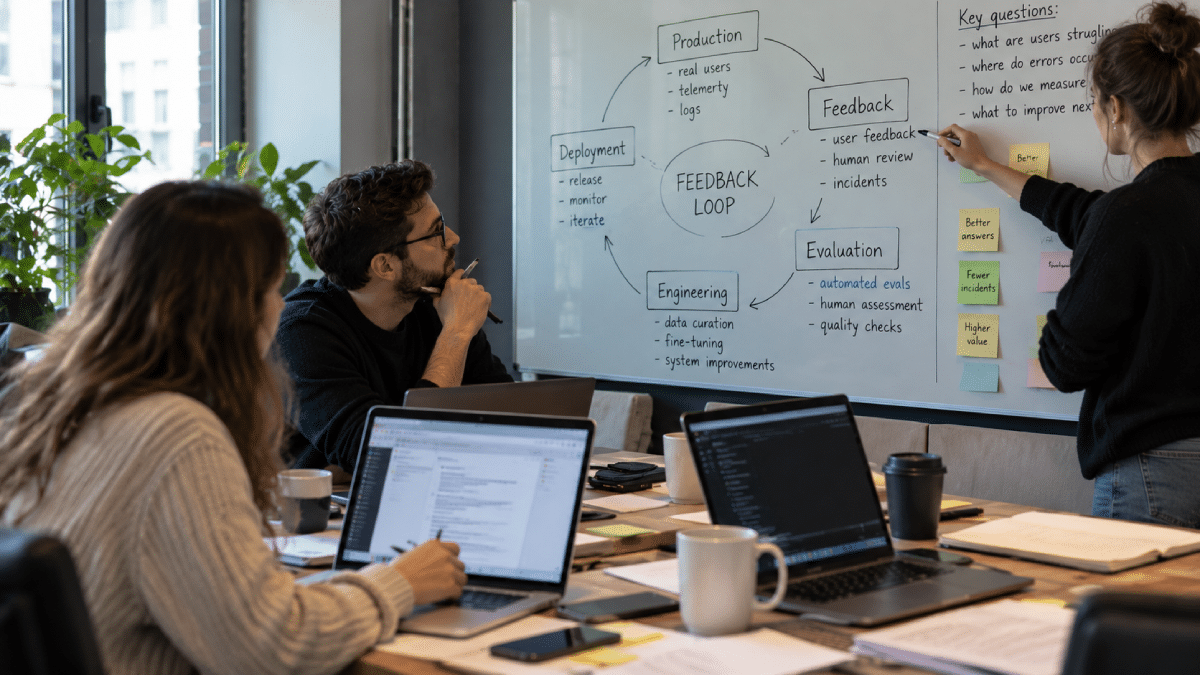
Deploying an AI system creates a source of information that simply does not exist during development: evidence about how the system behaves under real operating conditions. Users formulate requests that never appeared in evaluation datasets, retrieval systems encounter documents with unexpected structures, and agents discover execution paths that designers did not anticipate. Employees correct outputs, override decisions, abandon workflows, escalate cases and find ways to use the system that were never represented in the original requirements.
Production therefore does more than expose an AI system to traffic. It tests the assumptions on which the system was built and continuously generates evidence about where those assumptions hold and where they fail.
The difficulty lies in what happens to that evidence next. Many organisations collect large amounts of AI telemetry without creating an effective mechanism for turning it into improvement. Logs accumulate, users submit ratings, evaluation pipelines produce scores, incidents are investigated, product teams receive complaints and engineers discover recurring edge cases, yet these signals often remain disconnected from the process that actually changes the system.
A mature AI feedback loop closes that gap by connecting production behaviour with evaluation, diagnosis, engineering decisions, validation and controlled deployment. This is fundamentally different from assuming that an AI system should continuously retrain itself on whatever happens in production. In enterprise environments, the objective is rarely uncontrolled learning. It is controlled improvement based on production evidence.
Feedback Loops Begin After Deployment
Before production, teams work primarily with approximations of expected behaviour. Evaluation datasets represent anticipated usage, test scenarios model known workflows, red teams explore recognised risk categories and engineers construct edge cases based on what they believe might happen.
These practices are essential, but they cannot reproduce the full distribution of real-world behaviour. Actual users introduce far more variation. They ask ambiguous questions, combine several tasks into one request, provide incomplete information, use terminology that differs from internal documentation and attempt actions in unusual sequences. They may rely on outdated knowledge, misunderstand an interface or discover capabilities that designers never expected them to use.
The environment surrounding the system also changes. Enterprise documents are updated, APIs evolve, business rules are revised, products appear, permissions change, retrieval indexes are rebuilt and foundation models are upgraded. Tool schemas change, workflows expand into new departments and integrations that once behaved predictably may begin returning different results.
Production therefore becomes a continuous source of evidence about the relationship between the AI system and the environment in which it operates. The purpose of a feedback loop is to make that evidence operational.
A failed interaction should not disappear into a log archive, just as a repeated user correction should not remain isolated inside a conversation history. Patterns of unsuccessful tool calls should not become visible only when an engineer happens to investigate an incident. Relevant signals need a structured path back into the development and improvement process. That path is the feedback loop.
A Feedback Loop Is Not Automatic Retraining
One of the most important distinctions in enterprise AI operations is the difference between feedback and learning. The two terms are often treated as interchangeable, but they describe different processes.
A feedback loop captures evidence about system behaviour and uses that evidence to inform change. Retraining a model is only one possible response and, in many enterprise AI systems, it is not even the most likely one.
Suppose users repeatedly report that an enterprise knowledge assistant provides outdated policy information. It would be easy to conclude that the model needs improvement, but the actual cause may lie elsewhere. The retrieval system might be indexing an obsolete document, metadata filters could be selecting the wrong version, a reranker might favour an older but semantically similar source, the prompt may fail to prioritise effective dates or the application may be caching responses too aggressively.
Retraining the model would not necessarily solve any of these problems.
The same principle applies to agentic systems. If an agent repeatedly selects the wrong tool, the appropriate intervention may involve tool descriptions, schema design, routing logic, orchestration policy or task decomposition rather than the underlying model.
Enterprise feedback loops should therefore operate at the system level. A production signal enters the loop, the organisation determines whether it represents a meaningful failure, engineers diagnose where the behaviour originated and a change is proposed at the appropriate layer. That change is then evaluated against relevant cases before it becomes a candidate for production deployment.
A useful way to think about the process is:
production signal → evaluation → diagnosis → improvement → validation → controlled rollout
This is very different from:
user feedback → retrain model
The first creates an engineering control system. The second risks turning production noise directly into model behaviour.
Production Signals Are the Raw Material of Improvement
A useful feedback loop starts with signals, and those signals can originate from almost every layer of an AI system.
Explicit user feedback is the most obvious source. Users can rate an answer, report a problem, flag incorrect information or provide a correction. These signals are useful, but they represent only a small part of the available evidence.
User behaviour can often reveal more. Someone may immediately reformulate a question after receiving an answer, substantially rewrite an AI-generated document before using it or ignore a suggested response entirely. A workflow may repeatedly escalate after an AI interaction, while an autonomous action might be reversed shortly after execution. None of these events explicitly says that the AI failed, but patterns across them can reveal problems that direct ratings do not capture.
Operational systems provide another category of evidence. Retrieval traces show which documents were selected, tool traces reveal failed calls, unnecessary retries and unusual execution paths, while latency patterns can expose expensive branches of the workflow. Policy systems record blocked actions and review queues show where uncertainty or risk controls repeatedly require human intervention.
Semantic evaluation adds another layer by measuring qualities such as relevance, groundedness, completeness, instruction adherence, policy compliance or task-specific quality across production samples. These signals can reveal failures that neither infrastructure monitoring nor explicit feedback captures reliably.
Finally, downstream business processes provide evidence about actual outcomes. Did the support case reopen? Was the generated transaction reversed? Did an employee correct the extracted data? Did the user eventually find the information they needed? Did the workflow actually finish?
A mature feedback architecture does not assume that any one of these signals represents the truth. It combines them to create a stronger body of evidence.
Not Every Feedback Signal Deserves the Same Weight
Collecting feedback is relatively easy. Interpreting it correctly is much harder.
A thumbs-down reaction may indicate that an answer was wrong, but it may also mean that the user disliked a correct policy, expected a capability the system was never designed to provide or simply clicked the wrong control. A positive rating can be equally ambiguous because users may approve an answer that is fluent and convincing while still containing factual errors or unsupported claims.
Implicit signals require the same caution. A reformulated query may indicate that the previous answer failed, or it may simply reflect a change in the user’s goal. An escalation to a human can represent system failure, but it can also show that a deliberately designed safety or risk control worked exactly as intended.
Even expert feedback contains assumptions. Reviewers may disagree about completeness, relevance, acceptable uncertainty or the right course of action in an ambiguous case.
Feedback therefore needs context before it becomes useful evidence. Teams should know which application version produced the behaviour, which model and prompt were used, what context was retrieved, which tools were available, what policy decisions occurred, what type of task was being performed and what happened downstream.
Without that context, organisations risk optimising against noisy labels. This becomes particularly dangerous when feedback is incorporated automatically into training or evaluation datasets. Production data can contain biases, accidental interactions, malicious inputs, unusual edge cases and behaviour generated by earlier versions of the system. Treating all of it as equally valid learning material can reinforce precisely the behaviours the organisation wants to remove.
The purpose of feedback architecture is therefore not to maximise the amount of feedback collected. It is to improve the quality of evidence available for system improvement.
Evaluation Turns Feedback Into Evidence
A single failure rarely justifies a system change because it may represent a genuine defect or simply an isolated case. Enterprise teams need a way to determine whether production feedback points to a repeatable problem, and this is where evaluation becomes part of the loop.
Suppose several users report that an AI assistant gives incomplete answers about a particular internal process. The first response should not necessarily be to change the prompt. The organisation first needs to establish whether the problem can be reproduced, which task categories it affects, how frequently it occurs and whether it appears across different users, models, document collections or application versions.
Representative examples can then become part of an evaluation set. A proposed fix can be tested against those cases and against existing regression datasets to determine whether it solves the observed problem without degrading other capabilities.
This creates an important relationship between production and evaluation. Production reveals cases that development did not anticipate, evaluation turns those cases into repeatable tests and engineering uses those tests to validate changes. Production then provides evidence about whether the change behaves as expected under real conditions.
This is also why evaluation datasets should not remain static indefinitely. Production systems continually reveal new failure modes, user behaviours and operating conditions, so evaluation needs to evolve with them. That evolution, however, requires curation.
If every unusual interaction automatically becomes an evaluation case, the dataset quickly becomes noisy, repetitive or biased towards highly visible complaints rather than important operational failures. The goal is not to reproduce production traffic mechanically, but to convert meaningful production evidence into durable evaluation coverage.
Diagnosis Must Identify the Layer That Should Change
Detecting a problem is not the same as knowing what to fix. Modern enterprise AI systems contain many interacting components, and a weak answer can originate in the foundation model, retrieval, context construction, prompt logic, orchestration, tool behaviour, access control, business rules, application state or even the user interface.
Feedback loops become significantly more useful when they preserve enough execution context to distinguish between these possibilities.
Consider a drop in answer completeness. If the relevant source document never entered the retrieved context, there may be little reason to change the model. If the correct evidence was retrieved but truncated before generation, context management may be responsible. If the evidence was available and the model ignored it, prompt or model behaviour becomes a more plausible explanation. If the answer was correct but users consistently rated it poorly because the interface obscured citations, the best solution may sit entirely outside the AI layer.
This diagnostic step prevents organisations from treating the model as the universal explanation for system behaviour. It also changes the way improvement backlogs should be constructed. Ideally, a production issue should connect the observed behaviour with its execution trace, evaluation result, affected segment, likely failure layer and the evidence supporting that diagnosis.
That turns feedback from anecdotal reporting into engineering information. It also makes recurring patterns easier to identify. If apparently unrelated failures repeatedly originate from the same retrieval configuration or tool integration, the organisation can address the underlying problem rather than patching individual outputs.
Improvement Does Not Always Mean Changing the Model
Once a failure has been diagnosed, the organisation needs to decide which kind of intervention is appropriate. Model changes are only one possibility.
A retrieval problem may require better indexing, metadata, chunking, filtering, ranking or document lifecycle management. A tool-use problem may be solved through clearer schemas, stronger argument validation, better descriptions or different orchestration logic. Prompt-related failures may require revised instructions, examples, context ordering or output constraints, while policy problems might call for different escalation rules or additional approval boundaries.
Some failures are better solved at the interface level. If the system regularly receives incomplete input, asking the user a better clarifying question may be more effective than expecting the model to infer missing information.
In some cases, the best improvement is to reduce AI autonomy. If production evidence shows that a particular action produces too many costly exceptions, the workflow may be redesigned so that a human approves that step while AI continues automating the surrounding process. In other situations, the opposite may become justified because production evidence demonstrates that a previously supervised task has become consistently reliable.
Feedback loops therefore support architectural evolution. They provide evidence for deciding not only how model behaviour should improve, but how responsibility should be distributed between models, deterministic software, enterprise systems and people.
The strongest feedback loops improve the system as a whole rather than merely tuning the model.
Improvement Candidates Need Controlled Validation
Production evidence can identify a problem, but it cannot prove that a proposed fix is safe. Every change can introduce regressions.
A prompt adjustment that improves one task category may degrade another. A retrieval configuration that increases recall may add irrelevant context. A new model may improve reasoning while altering tool-use behaviour, and a stricter policy may reduce unsafe outputs at the cost of unnecessary refusals.
Feedback-driven development therefore needs a validation boundary between diagnosis and deployment. The first layer is usually controlled evaluation. A new configuration should be tested against the production-derived cases that motivated the change and against broader regression datasets representing important existing capabilities.
High-risk workflows may require expert review, while other changes can be tested under more realistic conditions without exposing all users immediately. Shadow execution can compare a candidate system with current production behaviour, canary deployments can limit exposure to a small portion of traffic and A/B experiments can measure differences where experimental design is appropriate.
The exact mechanism depends on the system and its risk profile, but the principle remains the same: feedback should generate hypotheses for improvement, not permission to deploy changes automatically.
This distinction becomes especially important when production signals are abundant. Without a controlled validation stage, an organisation can create a system that reacts constantly to recent behaviour and gradually accumulates unintended changes. Continuous improvement should not mean continuous instability.
Closing the Loop Requires Controlled Rollout
A feedback loop is not complete when engineers build a fix. It closes only when the organisation can determine whether the deployed change actually improved production behaviour.
That makes versioning essential. Teams need to know which model, prompt, retrieval configuration, orchestration logic, policy set and application version produced each relevant execution. Without this information, post-deployment comparisons become ambiguous.
A candidate version may perform well in offline evaluation and still behave differently under production workload. Real user behaviour may diverge from test scenarios, external tools may respond differently and traffic composition may expose cases that were absent from evaluation.
Controlled rollout limits the consequences of that uncertainty. A change can initially be introduced to a subset of traffic or users while the organisation compares relevant metrics, semantic evaluations, failure rates, operational costs and downstream outcomes. If behaviour deteriorates, rollback should be possible. If it improves, deployment can expand gradually.
The production evidence generated by the new version then becomes input to the next cycle. This is the operational meaning of a closed feedback loop: it does not assume that every iteration succeeds, but it ensures that the organisation can determine whether it did.
Human Feedback Is Valuable Precisely Because It Is Imperfect
Human feedback remains important in enterprise AI because many relevant qualities cannot be measured reliably through deterministic rules alone. A domain expert may recognise that an answer is technically correct but operationally misleading, an employee can identify missing context that an automated evaluator does not understand and a compliance specialist may detect risk in an otherwise fluent response.
Human judgement, however, should not be treated as unquestionable ground truth. People disagree, apply different standards and interpret instructions differently. Their assessments can also depend on experience, context, workload and incentives.
Human feedback therefore needs structure. Reviewers should know what they are evaluating and according to which criteria, while important disagreements should remain visible rather than being silently averaged away. High-risk domains may require adjudication or multiple reviewers.
It is also useful to distinguish between user and expert feedback. Users provide valuable evidence about usefulness and interaction quality, whereas domain specialists may be better positioned to judge correctness, compliance or process validity. Neither perspective replaces the other.
The strongest feedback systems preserve these distinctions and combine human signals with automated evaluation, system telemetry and downstream outcomes. The goal is not to identify a single perfect source of feedback, but to assemble enough independent evidence to support better engineering decisions.
Agentic Systems Need Feedback at the Action Level
Feedback becomes more complex when AI systems move from generating information to performing actions. A chatbot can often be evaluated primarily through its responses and their consequences, while an agent produces complete execution trajectories.
It may plan, select tools, retrieve information, call APIs, modify enterprise data, request approvals, retry failed operations and decide when a task is complete. A successful final result does not necessarily mean that the trajectory was good. The agent may have made unnecessary calls, selected an inefficient route, attempted a prohibited action before being blocked or required repeated retries.
The reverse is also possible. A failed outcome may still contain useful evidence showing that several intermediate decisions were correct and that one specific tool interaction caused the failure.
Agentic feedback loops therefore need to operate at several levels. The organisation needs evidence about the final outcome, but also about the sequence of decisions that produced it. Which tool was selected? Were its arguments valid? Did the tool return the expected result? Was the next action appropriate given that result? Did the agent recognise when escalation was necessary? Did a human later override or reverse the action?
This makes execution traces central to feedback architecture. Without them, teams may know only that an agent succeeded or failed. With them, they can determine which specific decisions should influence the next improvement cycle.
As autonomy increases, this distinction becomes more important because feedback is no longer only about what the system said. It is increasingly about what the system did.
Feedback Loops Need Governance and Ownership
A feedback loop connects production behaviour to system change, which makes it a governance mechanism as much as an engineering mechanism.
Someone needs to decide which production signals matter, how evaluation criteria are defined and whether an observed failure represents acceptable variance, an engineering defect, a governance issue or a change in business requirements. Someone also needs the authority to approve the resulting changes.
Without clear ownership, feedback accumulates without resolution. Product teams may prioritise user complaints, engineering teams may focus on reproducible technical failures, risk teams may care most about low-frequency but high-impact events and business owners may focus on downstream outcomes. All of these perspectives can be valid, but the feedback process needs a way to reconcile them.
This becomes particularly important when an improvement changes system behaviour rather than simply correcting a defect. A new prompt may alter tone and decision boundaries, a model upgrade may change refusal behaviour, a new retrieval source can expose additional information and an agent policy may expand the set of actions that can be performed without approval.
These are not merely implementation details. They change the operating characteristics of the AI system.
A mature feedback architecture should therefore record not only what changed, but why it changed, which evidence supported the decision, who approved it and what validation results were available. This creates an auditable history of system evolution.
Feedback Loops Should Connect to AI Observability
Feedback loops depend on the ability to reconstruct what happened, which makes observability their operational foundation.
A user complaint without an execution trace may be difficult to reproduce. A quality score without information about the model, prompt, retrieval process and tool calls can reveal deterioration without explaining the cause. A failed agent task without trajectory data provides little information about which decision led to the failure.
AI Observability in Enterprise Systems provides the broader architecture needed to connect these signals across production executions. Within that architecture, Semantic Monitoring for AI Applications can identify changes in qualities such as relevance, groundedness, completeness or task alignment that infrastructure telemetry alone cannot capture.
Feedback loops operate downstream of these capabilities. Observability exposes behaviour, evaluation determines whether that behaviour represents a meaningful problem and feedback architecture determines what the organisation does with the resulting evidence.
This separation matters because monitoring without an improvement process creates visibility without adaptation, while improvement without observability leads to changes without sufficient evidence. The two capabilities become substantially more useful when designed together.
The Best Feedback Loop Improves the System, Not Only the Model
Enterprise AI systems should not be expected to improve simply because they are exposed to more production data. Experience creates value only when the organisation can interpret it and translate it into controlled change.
A mature feedback loop captures meaningful production signals, connects them to execution context, evaluates whether they represent recurring problems, diagnoses the responsible system layer, proposes an appropriate intervention, validates that intervention against relevant cases and deploys it under controlled conditions.
Sometimes the result will be a model change, but often it will not. The retrieval layer may be redesigned, the prompt revised, a tool contract changed, a policy tightened, an approval step introduced or the interface adjusted to ask a better question. An unreliable autonomous action may return to human control, while a previously supervised task may become more autonomous after sufficient evidence of reliability.
This is why enterprise AI feedback loops are better understood as an operating capability than as a model-training technique. Their purpose is not to make AI systems change continuously, but to help organisations learn systematically from production behaviour.
That distinction becomes more important as enterprise AI architectures grow in complexity. The more components a system contains, the less useful it becomes to treat every failure as a model problem. The more autonomy the system receives, the more important controlled validation and rollout become. The more consequential the workflow, the more dangerous it is to convert noisy feedback directly into behavioural change.
Continuous improvement therefore requires more discipline than continuous learning. Production reveals what the organisation did not anticipate, observability preserves the evidence, evaluation determines what matters, diagnosis identifies what should change, validation tests whether the proposed change is actually better and controlled rollout determines whether that improvement survives contact with production.
Then the cycle begins again.
That is how enterprise AI systems become more reliable over time: not because they learn automatically, but because the organisations operating them develop a systematic way to learn from production and improve them.